The problem
One VPS hosts the CRM, the academy, several bots and the marketing site. “Is everything up?” meant SSH-ing in and running six commands; a full disk or an expired certificate was found by a user first.
What I built
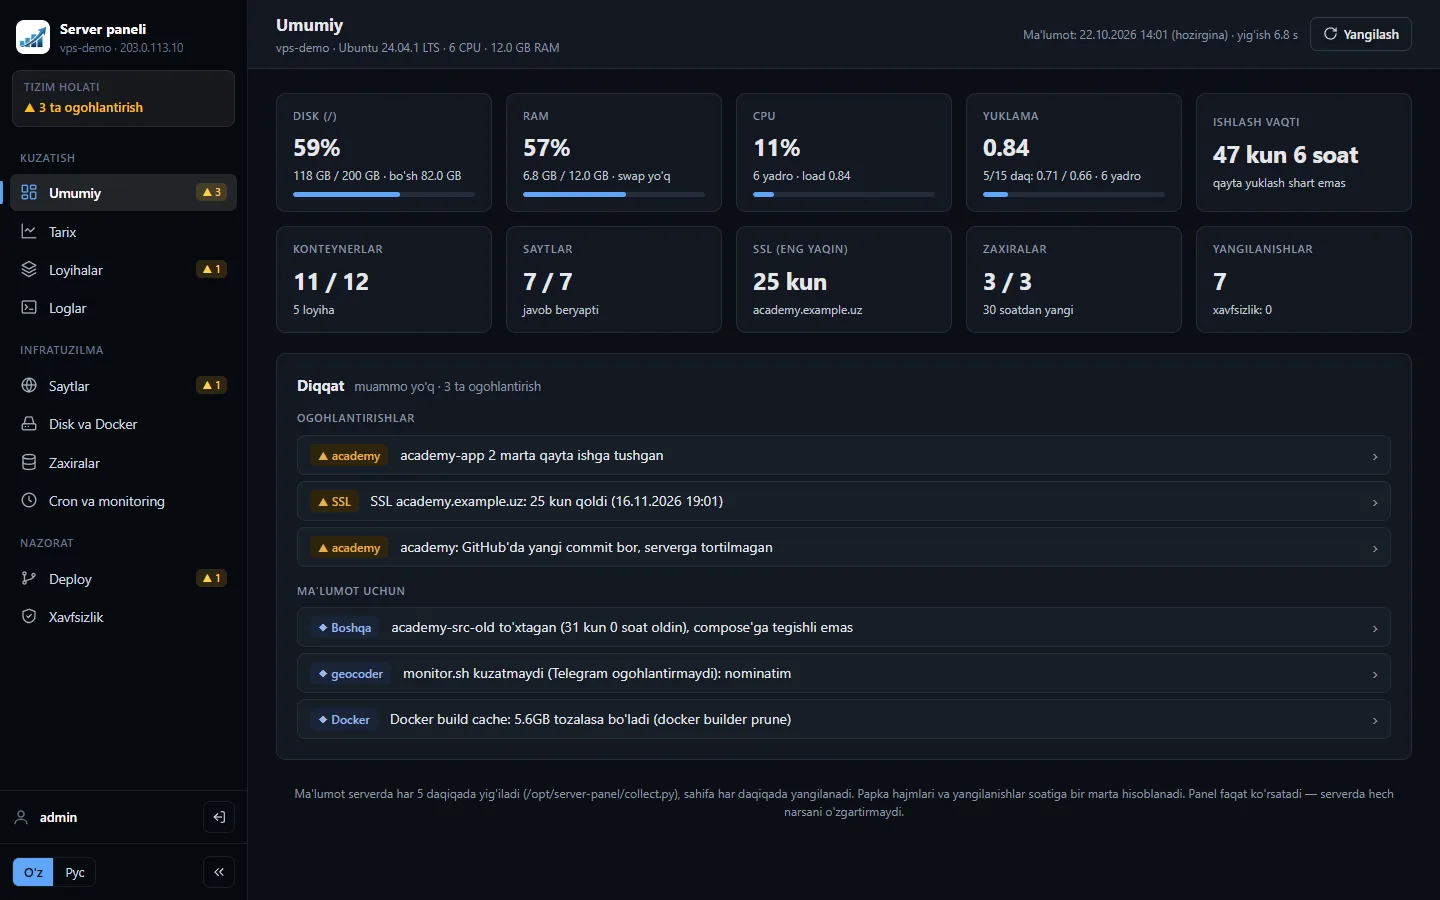
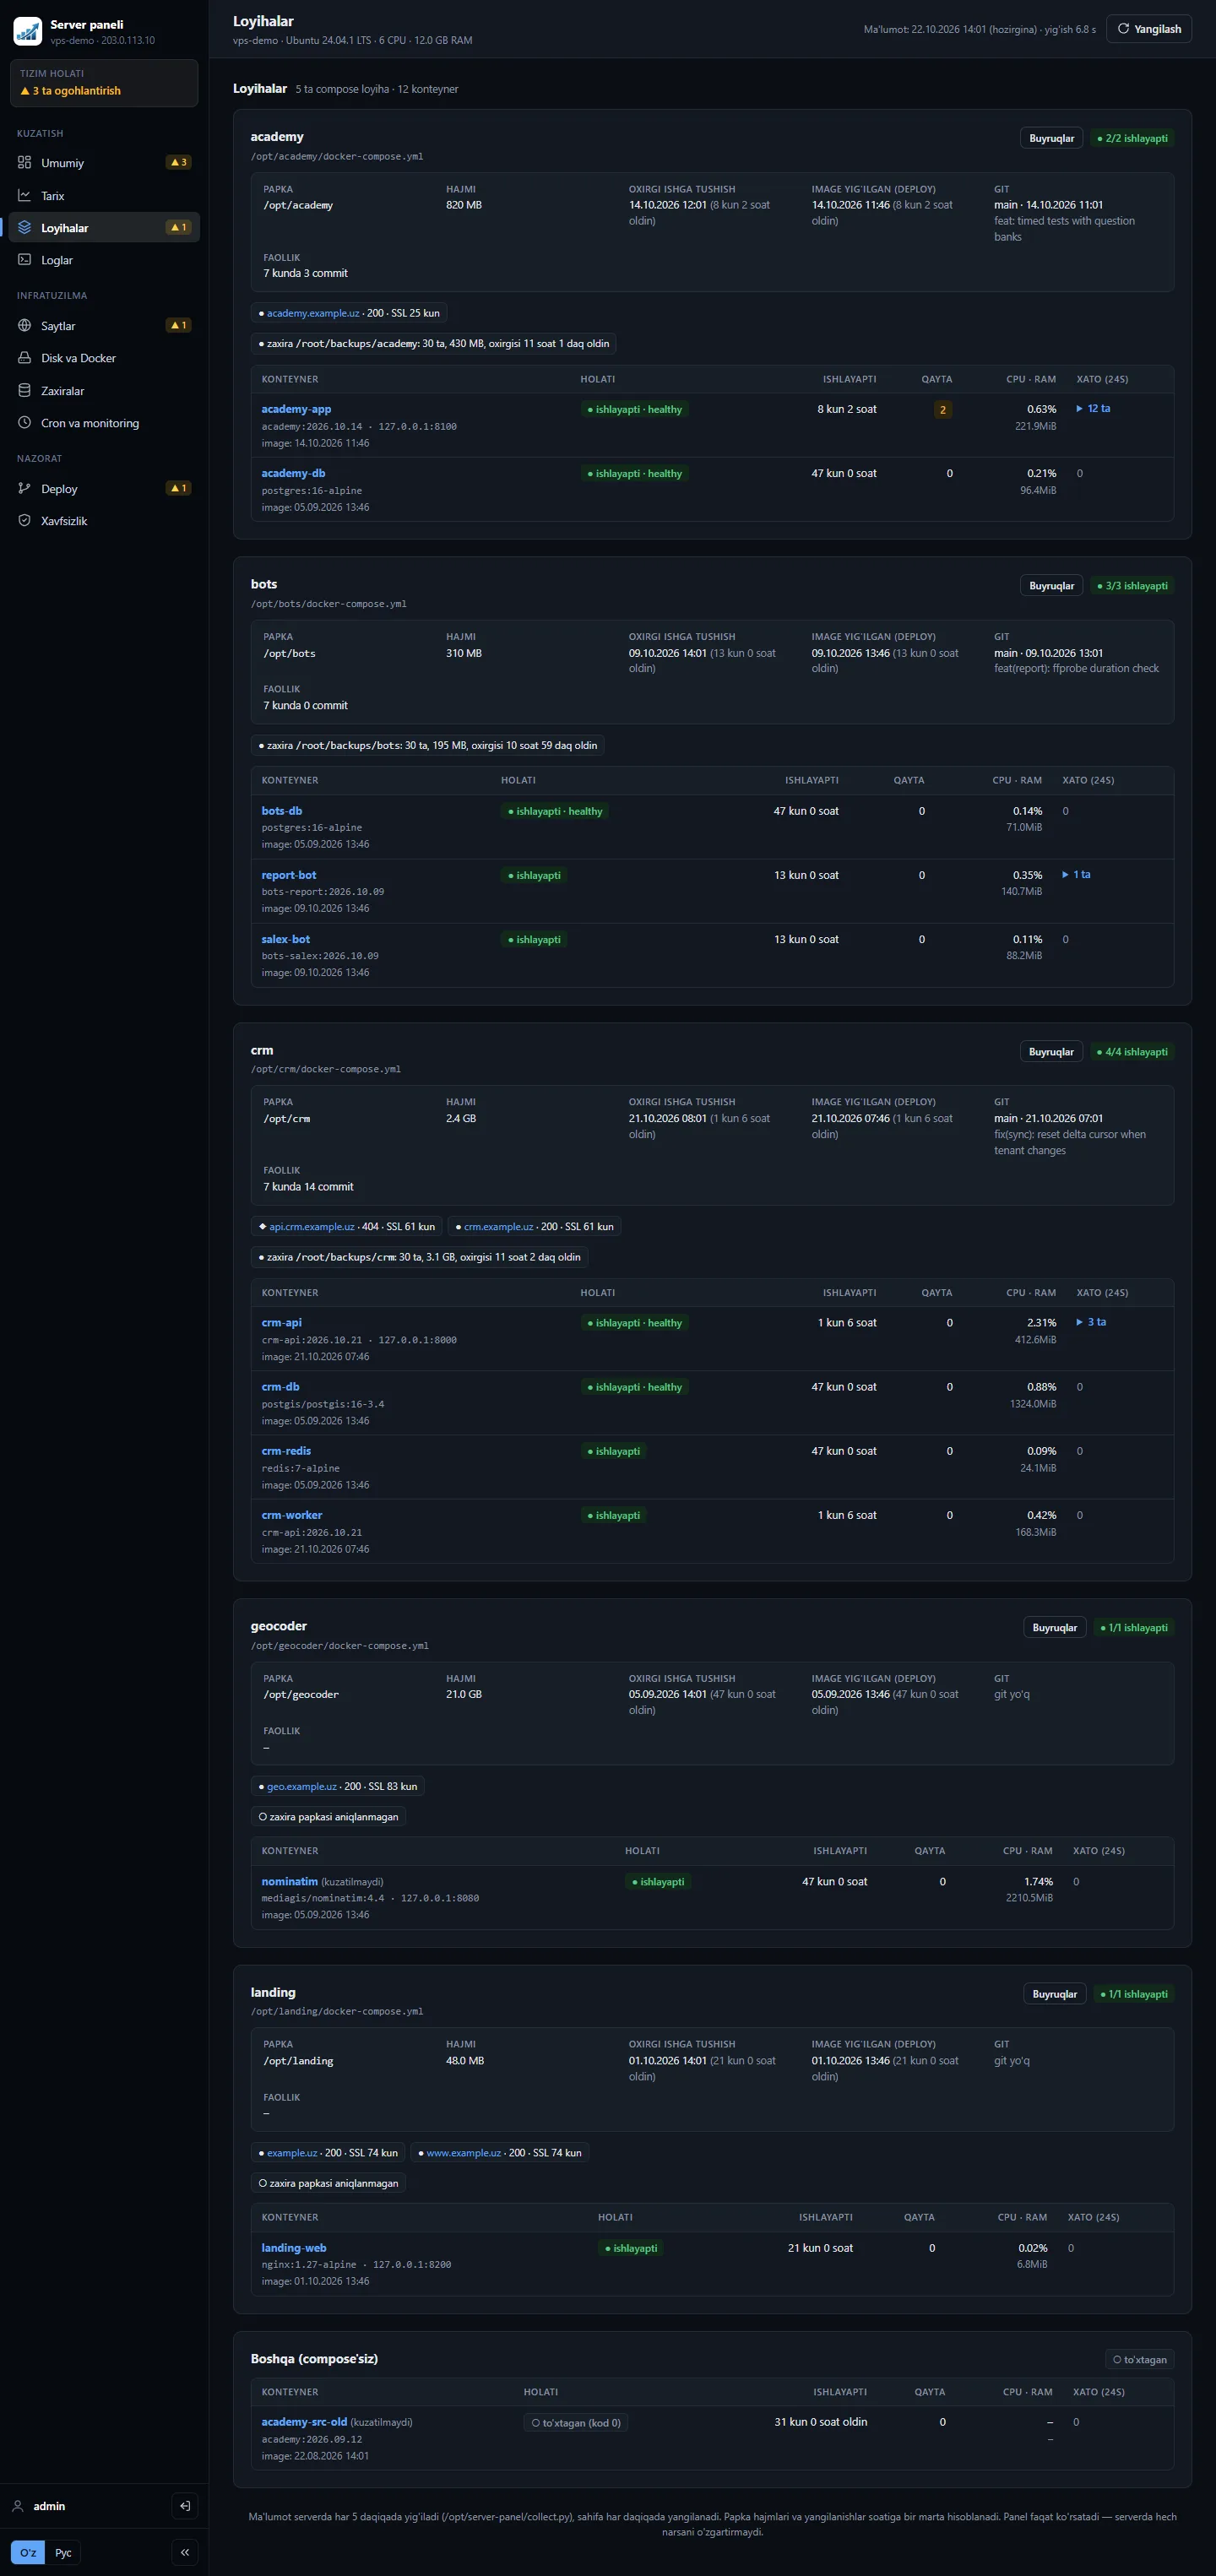
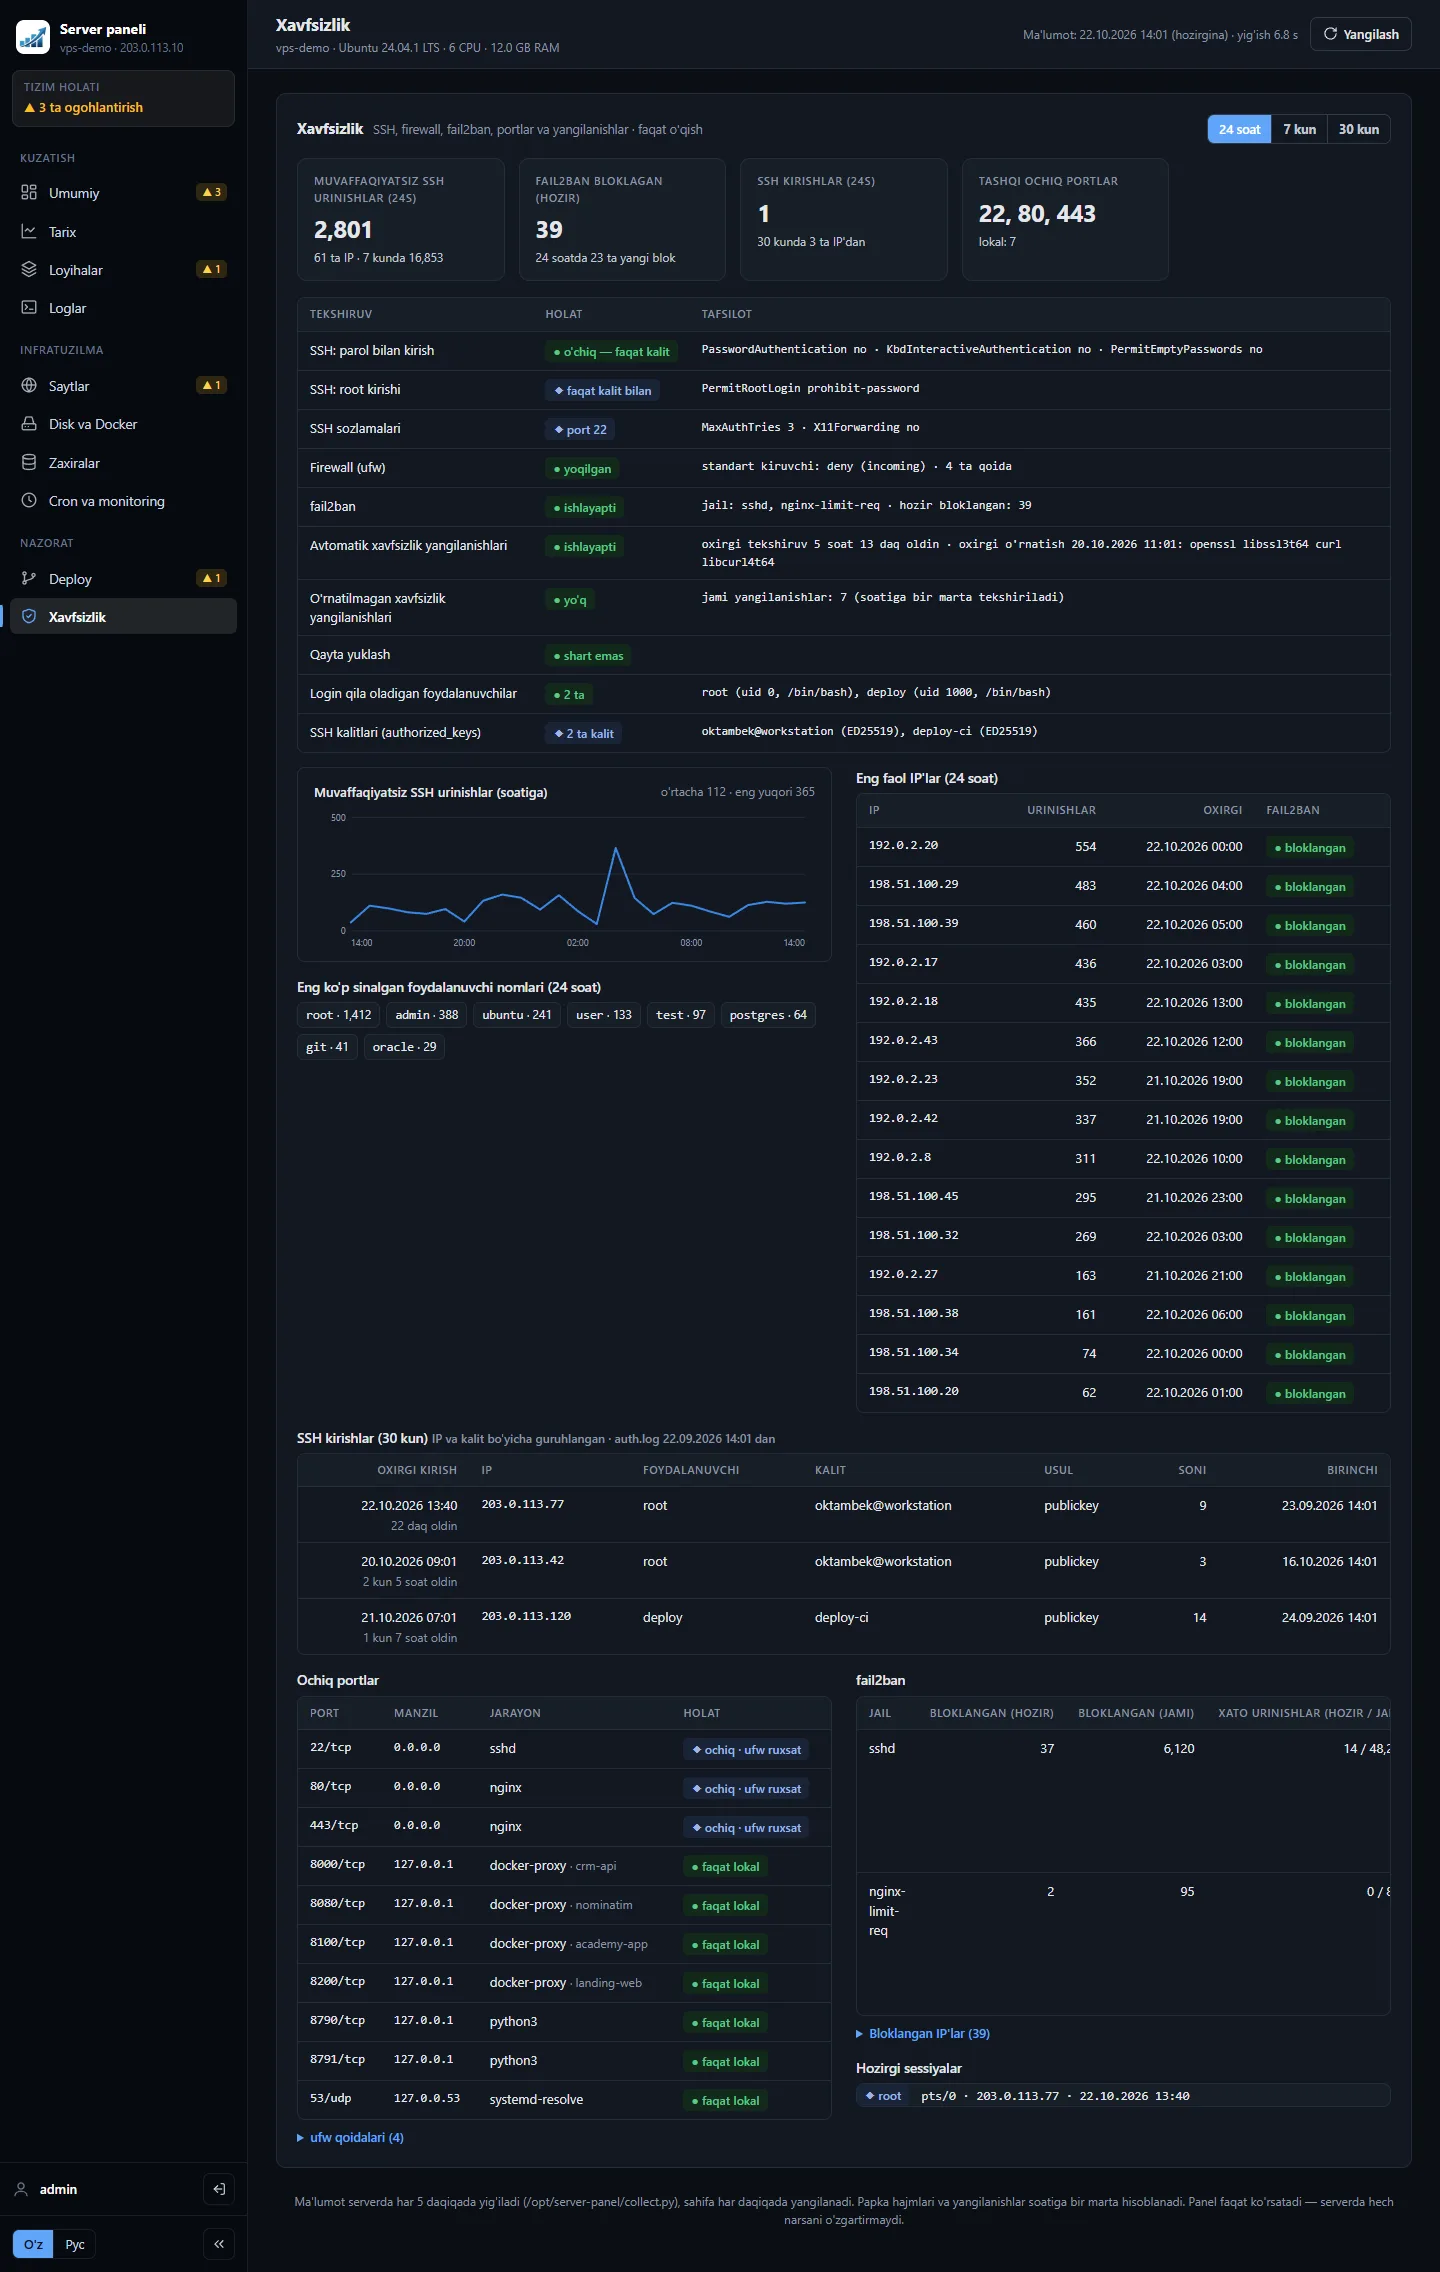
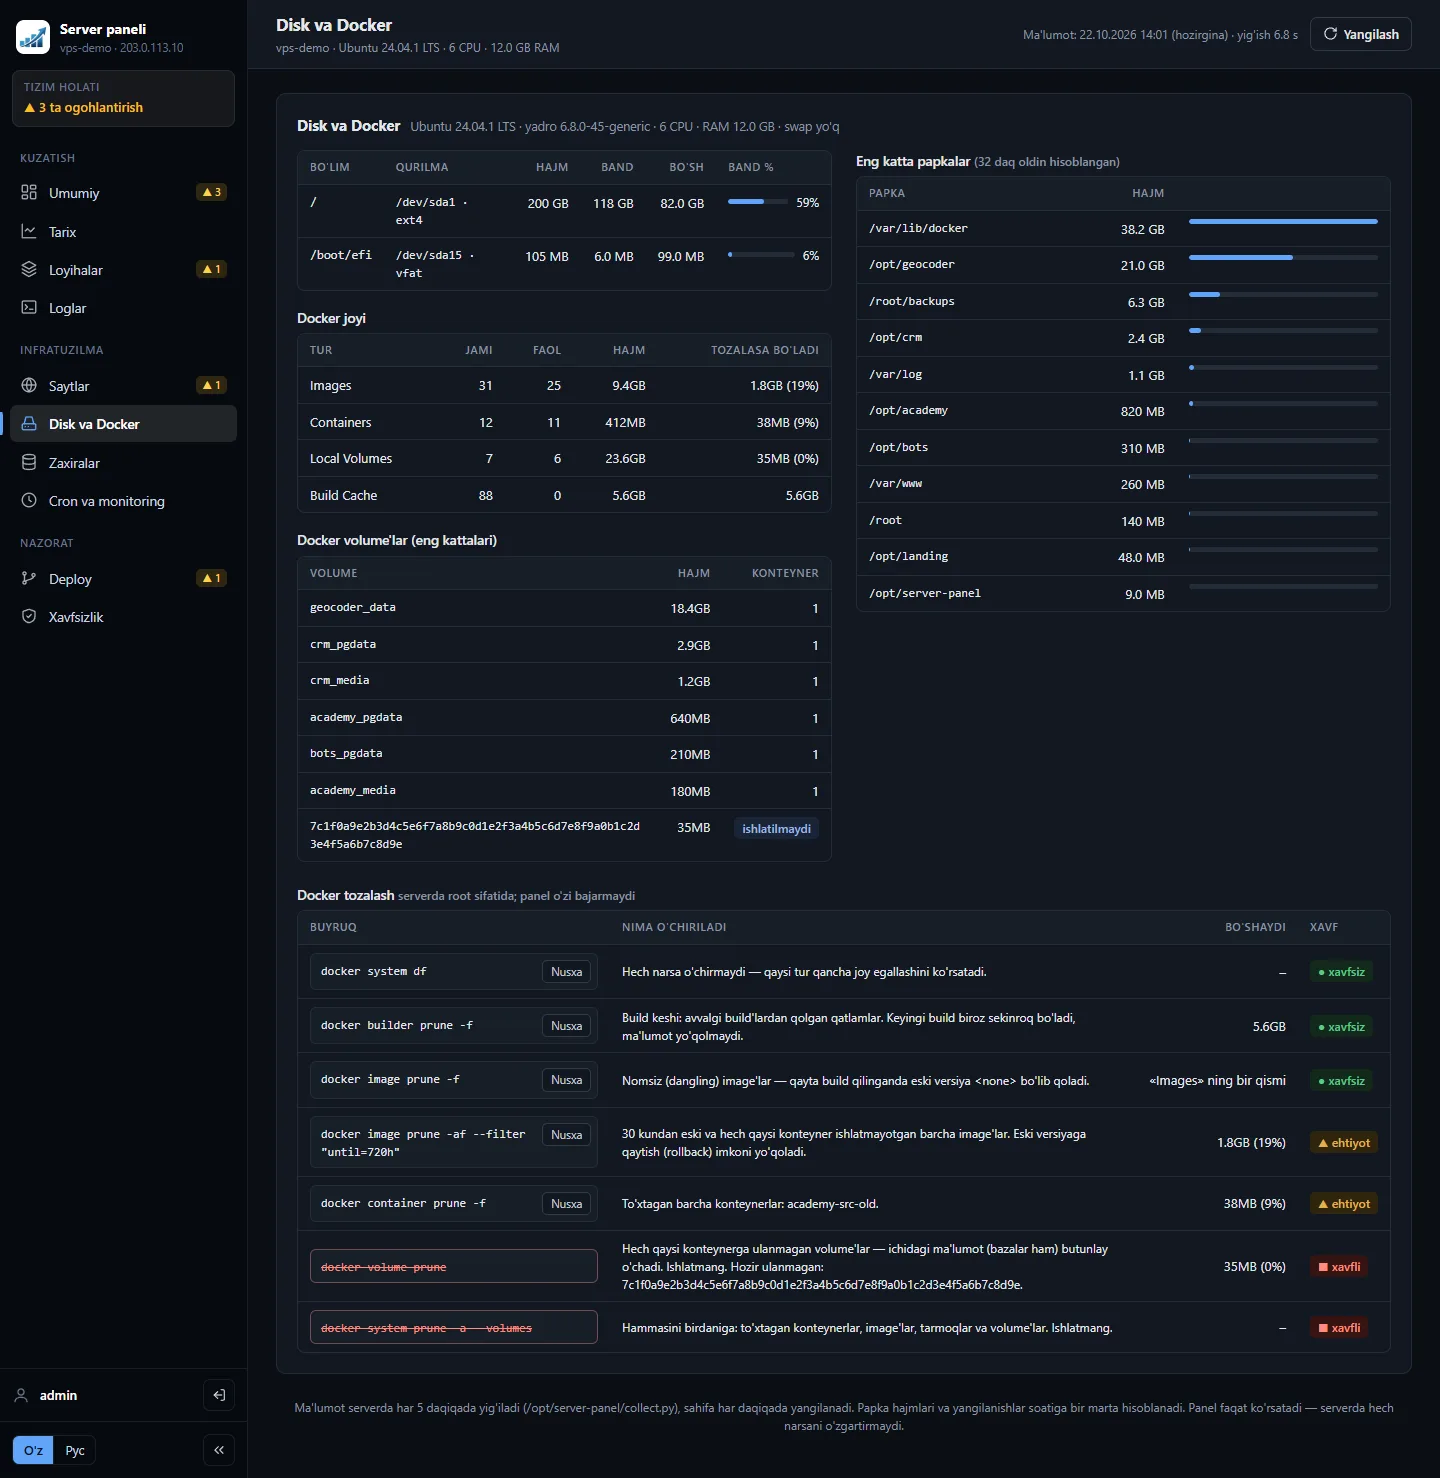
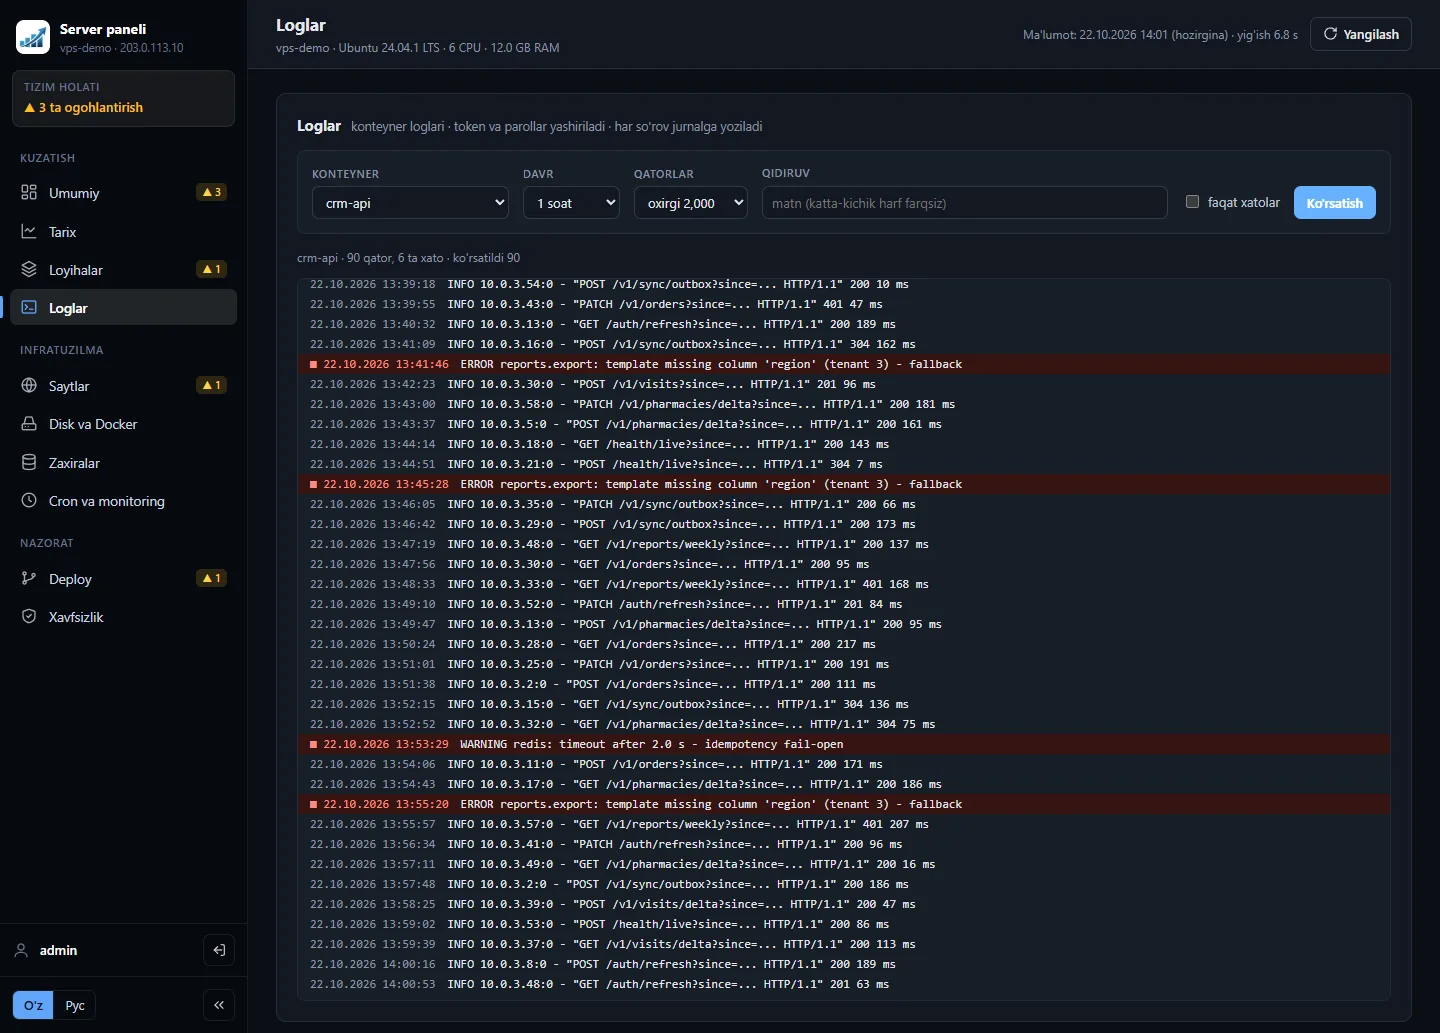
- A collector in plain Python 3 (no dependencies) run by root cron: containers and their
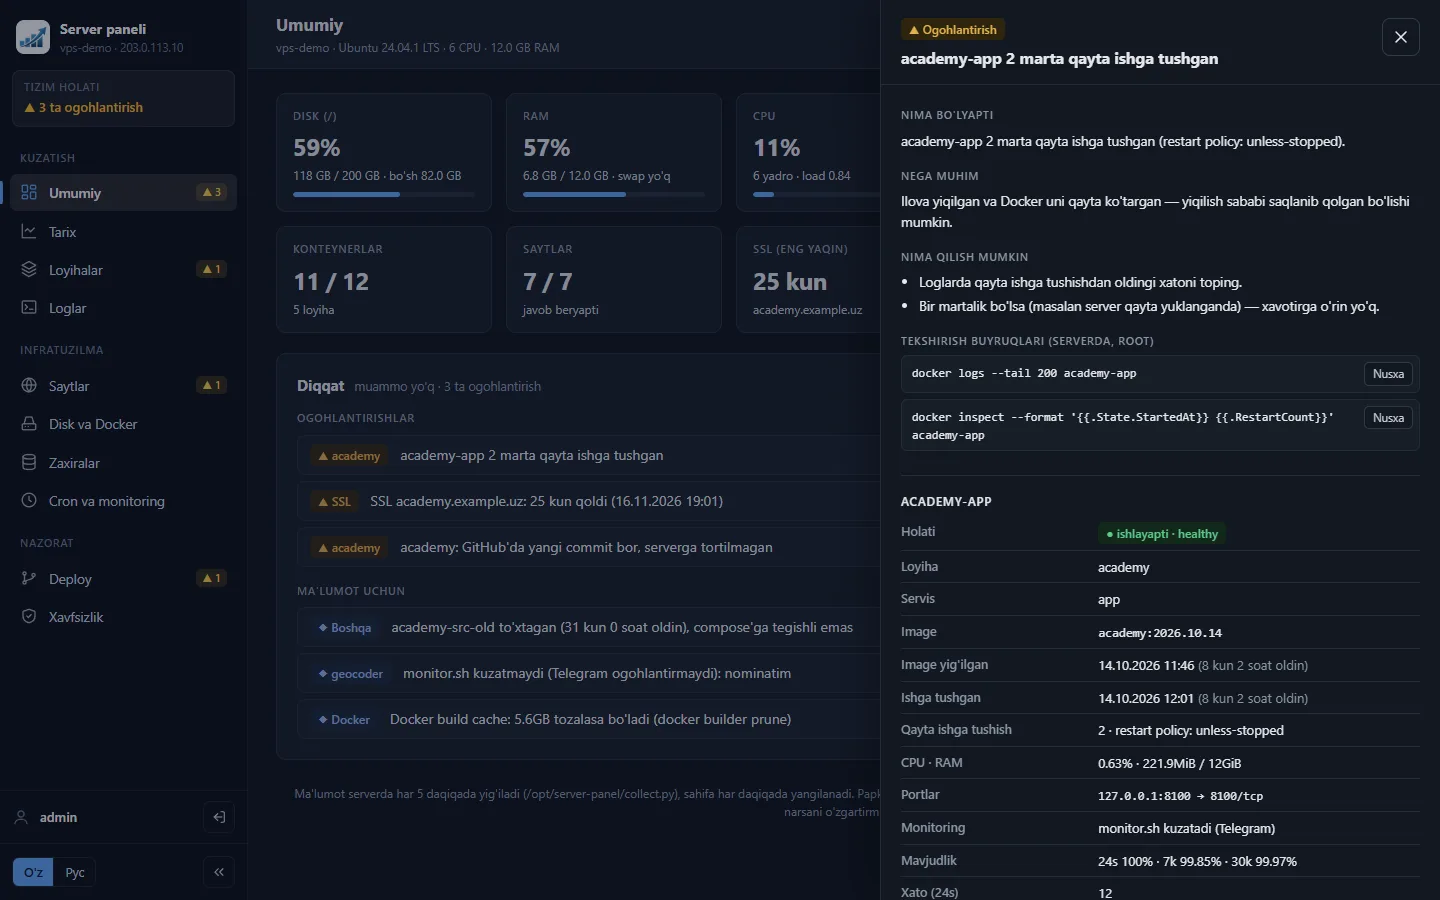
images, CPU/RAM/disk/load, every site’s HTTP status and certificate expiry, backup freshness, cron
and
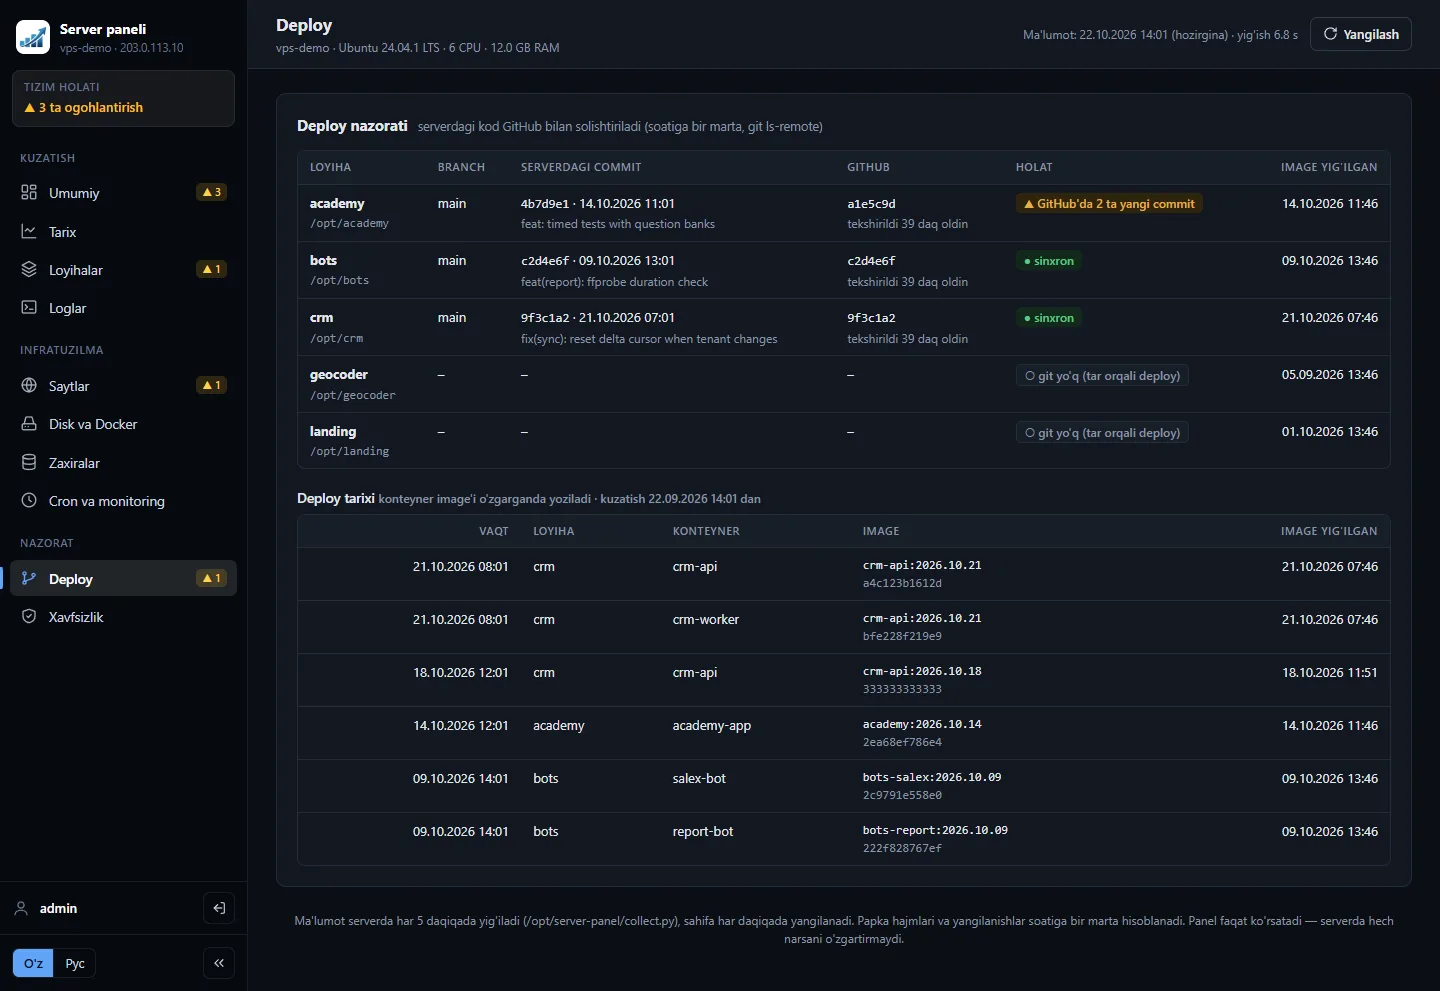
monitor.shalerts, SSH configuration and recent logins, failed attempts, fail2ban, ufw and open ports, unattended upgrades. - Deploy drift: the commit running on the server versus the latest commit on GitHub, per project, with deploy history — so “did the deploy actually happen?” has an answer.
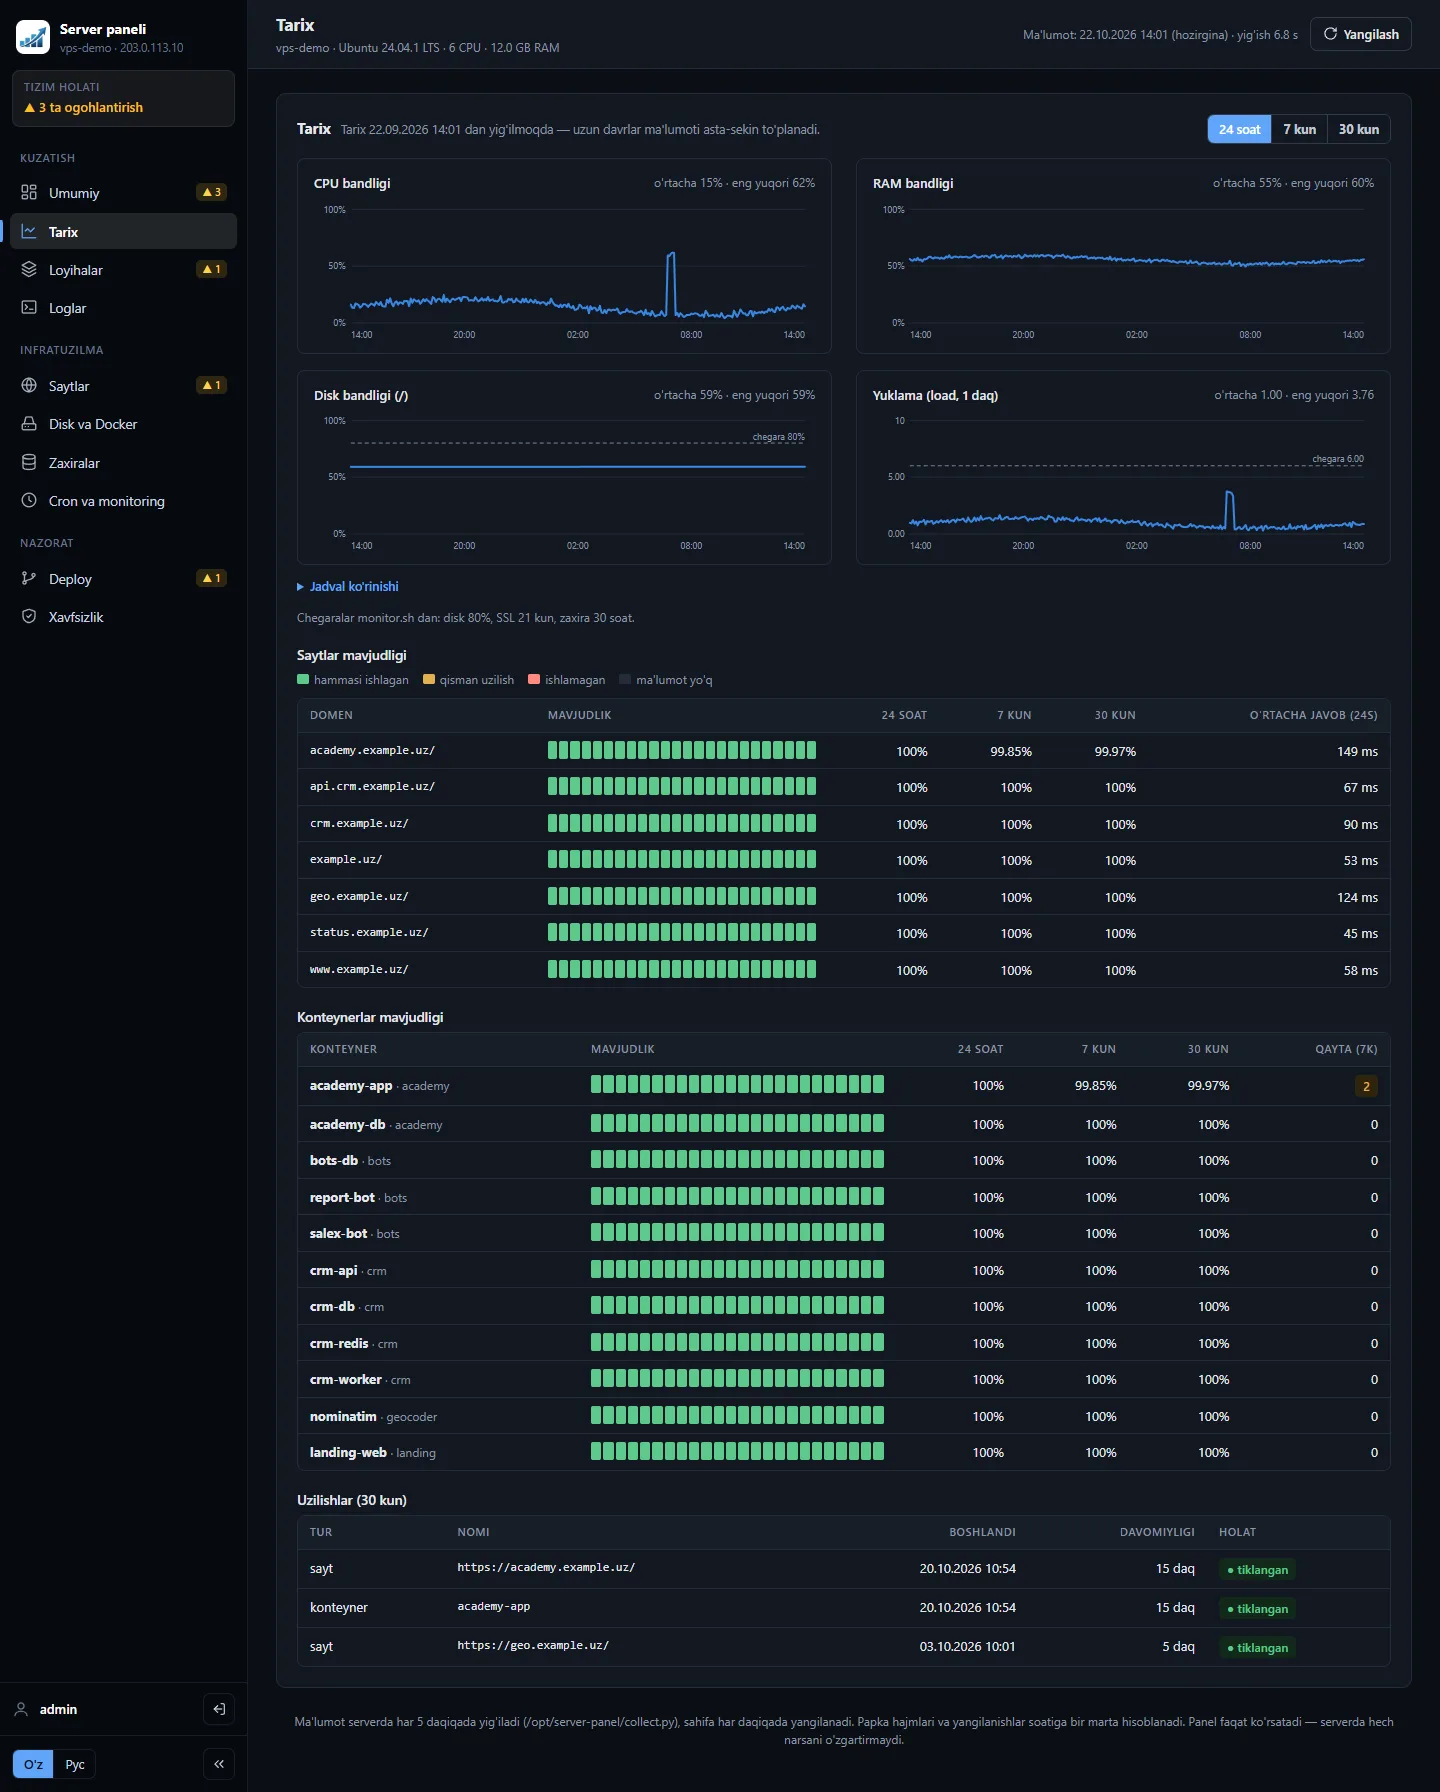
- History for 24 hours / 7 days / 30 days with charts, uptime per site and container, and an incident list.
- A small web panel (Uzbek / Russian) behind login, each section its own page, with the number of problems shown in the menu. The panel changes nothing on the server: a separate control service with a restricted sudoers file exposes only the actions that are safe.
Why it matters
It is the operations half of running products alone: the same discipline as the launch-readiness checklist for LM-CRM, turned into something that watches continuously.